#devchallenge #hf26challenge Slow & Steady

LazyDecider

I go to sleep. An open-weight agent fine-tunes a model for me β€” proposing configs, pruning the losers, and leaving a report by morning. No cloud bill. It all runs on a laptop.

πŸ¦₯ Gemma 4 E4B proposes β†’ βœ‚οΈ ASHA prunes β†’ πŸ”¬ Tinker confirms
A sloth in a hammock watching config cards get kept or reverted

πŸ“Š The full walkthrough β€” slides + a live playground demo, ~3.5 min

A deeper tour: the task, the model, the exact configs Gemma proposed, the ASHA keep/revert calls, the β€œcan’t cheat” guardrails, every sealed-test number β€” and a live finale running the real model on three invoices.

β–Ά Open the slide deck Download the narrated video (MP4)

The overnight loop β€” replayed from the real log

Gemma reads its own history and proposes one config at a time, with a one-line reason. The ASHA pruner trains it, and we keep it only if it beats the best on a frozen split β€” otherwise revert.

Invoice processing β€” the model's strongest domain β€” 0.840 on the sealed test

1 / 6

Invoice processing is one of the decision domains in the training set, and it's where the model does best β€” 0.840 on sealed invoice-processing cases. Step through real sealed cases: the model reads an invoice against its purchase order and makes the accounts-payable call. Gold = the teacher consensus.

β–Ά Try it yourself

Run the real model on your own invoice β€” a local Gradio playground with sliders for invoice total, PO total, quantities, due dates and vendor history. Three commands on a Mac (Apple-Silicon MLX build):

git clone https://github.com/rahuls321/autoresearch-finetune-lab
cd autoresearch-finetune-lab
uv venv --python 3.12 .venv && uv pip install --python .venv/bin/python unsloth gradio
.venv/bin/python src/playground.py            # opens http://127.0.0.1:7860
# add --share for a temporary public link

The playground loads artifacts/best_model and returns calibrated probabilities for all five accounts-payable decisions β€” the same model behind the 0.840 number above.

Progress & results β€” every number self-measured on a sealed test

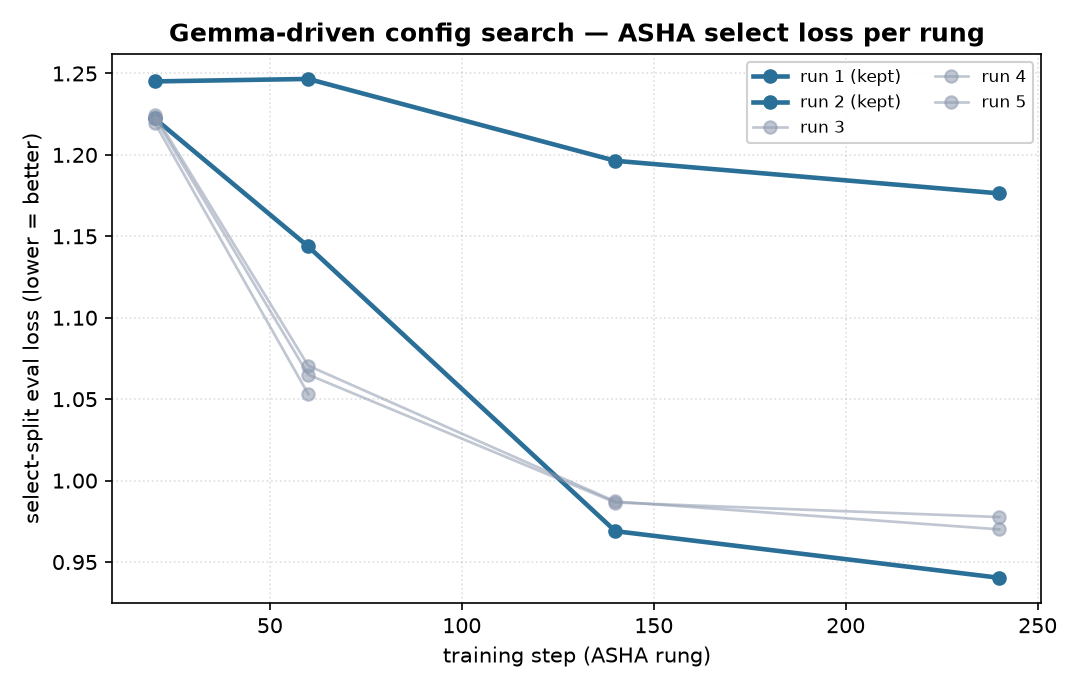
ASHA select-loss curves per Gemma-proposed config
Run 2 β€” Gemma unfreezes the backbone with LoRA β€” drops validation loss 1.04 β†’ 0.84, the night's biggest jump.
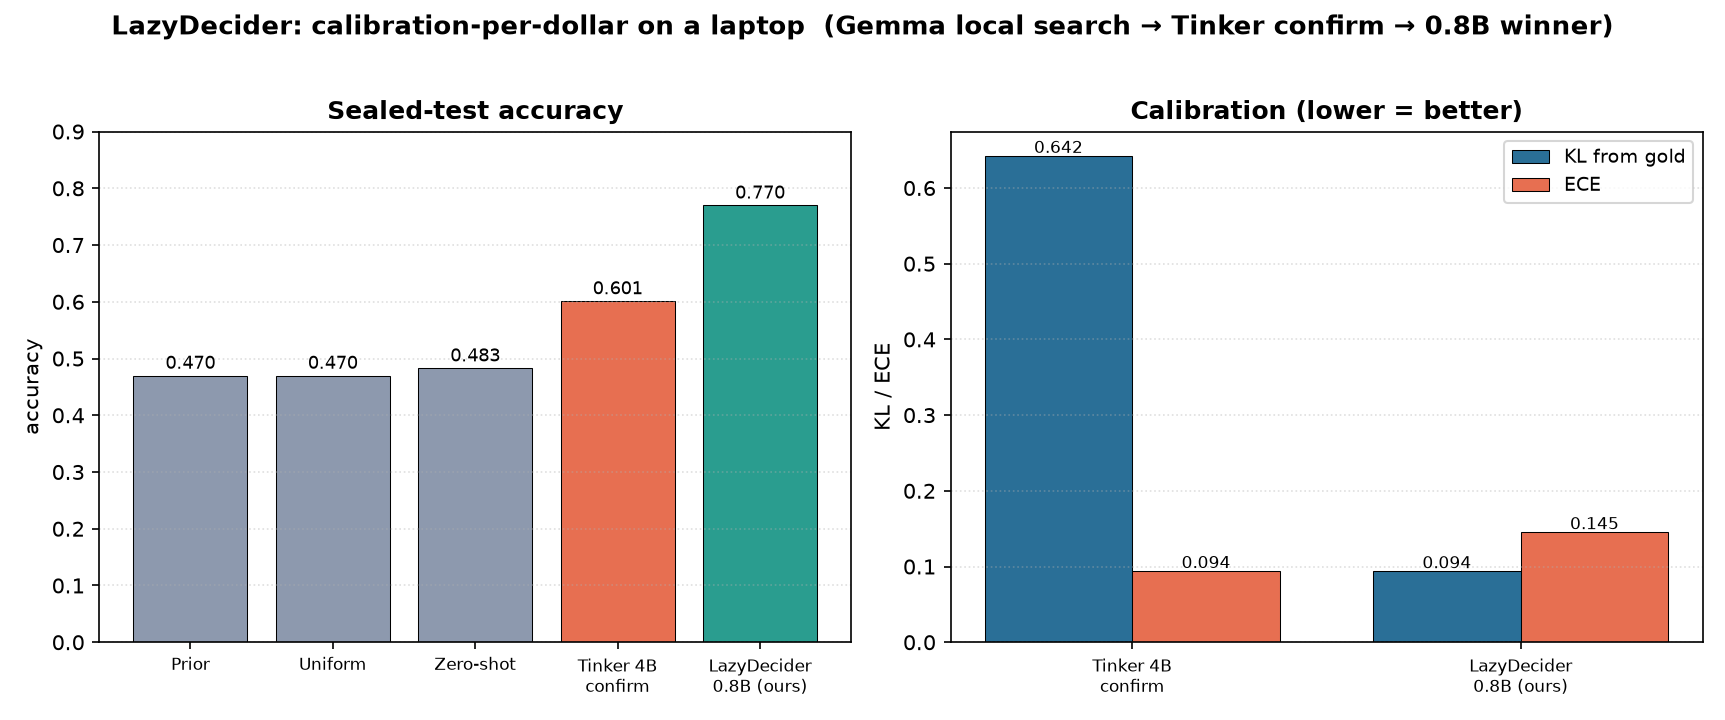
Sealed-test accuracy and calibration comparison
The 0.8B winner lands 0.770 accuracy with a very low KL-from-gold of 0.094.

Sealed-test results

ModelRoleAccuracy ↑KL ↓Brier ↓ECE ↓

The headline is the KL from gold of 0.094 on a 0.8B model found autonomously, for ~$0, on an 18 GB Mac. Tinker independently confirms a clear lift over zero-shot.

The "can't cheat" part